
 Muhammad Saad
 Summarize in ChatGPT
BERT is a bidirectional Transformer language model that helps computers understand word meaning from left-side and right-side context in a sentence. Google uses BERT as an AI system for understanding how word combinations express meaning and search intent, especially in natural-language queries.
BERT changed search because many queries do not depend on one keyword. Many queries depend on word relationships. “To,” “for,” “no,” “with,” and “without” can change the required result. Google stated that BERT models help Search understand these relationships in ranking and featured snippets.
What is BERT?
BERT is Bidirectional Encoder Representations from Transformers, a neural language model that learns contextual word representations from unlabeled text. BERT reads words before and after a target word, so the same word can receive different meanings in different sentences.
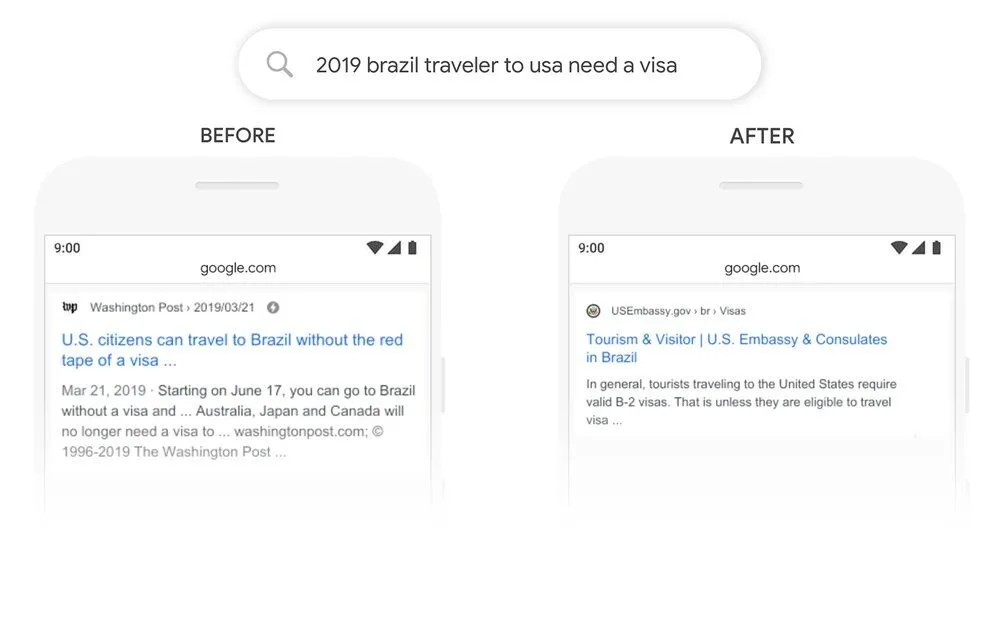
In one example, “to” changed the travel direction in a visa query. In another example, “no” changed the meaning of a parking query. These small words affect intent, so BERT helps Search avoid shallow keyword matching.
BERT belongs to natural language processing. Natural language processing connects language, meaning, context, entities, and tasks such as question answering, language inference, sentiment classification, and named entity recognition.
A simple BERT meaning table is below.
| BERT element | Meaning | Function |
|---|---|---|
| Bidirectional | Reads left and right context | Understands word relationships |
| Encoder | Transformer encoder structure | Converts text into contextual vectors |
| Representations | Numerical meaning signals | Stores word and sentence meaning |
| Transformers | Attention-based architecture | Connects words across a sequence |
Who firstly introduce BERT?
BERT was first introduced by Jacob Devlin, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova from Google AI Language in 2018. The research paper was titled “BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding.”
The paper introduced BERT as a model that pre-trains deep bidirectional representations from unlabeled text. The paper reported state-of-the-art results on 11 natural language processing tasks, including GLUE, MultiNLI, SQuAD v1.1, and SQuAD v2.0.
What is the history Of BERT?
The history of BERT is the movement from one-direction language modeling to deep bidirectional language understanding. Earlier language models mainly processed text from left to right or used separated left-right representations. BERT used masked language modeling to train one model on both directions together. Google’s 2019 Search announcement said BERT affected 1 in 10 U.S. English searches at launch, mainly longer and conversational searches where small connecting words affected meaning.
BERT’s history has 5 main stages.
- Transformer foundation: Transformer architecture gave BERT its encoder structure and attention mechanism.
- Generative pre-training stage: Earlier models used left-to-right language modeling for transfer learning.
- BERT introduction: Google AI Language introduced BERT in 2018 with masked language modeling and next sentence prediction.
- Search use: Google announced in 2019 that BERT was applied to Search ranking and featured snippets.
- BERT family growth: Researchers created many BERT variants for speed, compression, training efficiency, domain adaptation, and multilingual understanding.
How BERT Were Trained?
BERT was trained with unlabeled text, masked language modeling, and next sentence prediction. The original BERT paper used BooksCorpus with 800 million words and English Wikipedia with 2.5 billion words as pre-training data. BERT training teaches 2 language skills. First, masked language modeling teaches word meaning from surrounding context. Secondly, next sentence prediction teaches sentence-pair relationships for tasks such as question answering and language inference.
BERT training has 5 main steps.
- Collect text corpus: Use document-level text from BooksCorpus and English Wikipedia.
- Tokenize words: Use WordPiece tokenization with a 30,000-token vocabulary.
- Mask tokens: Select 15% of WordPiece tokens for prediction.
- Predict masked words: Replace selected tokens with
[MASK]80% of the time, random tokens 10% of the time, and unchanged tokens 10% of the time. - Predict sentence relation: Use next sentence prediction with 50% real next sentences and 50% random sentences.
What is the Architecture of BERT?
The Architecture of BERT is a multi-layer bidirectional Transformer encoder. BERT uses self-attention, token embeddings, segment embeddings, position embeddings, [CLS] classification token, and [SEP] separator token.
The original paper reported 2 main BERT architecture sizes.
| BERT architecture | Layers | Hidden size | Attention heads | Parameters |
|---|---|---|---|---|
| BERT Base | 12 | 768 | 12 | 110 million |
| BERT Large | 24 | 1024 | 16 | 340 million |
How Many Variants Of BERT?
There is no fixed official total number of BERT variants, because BERT became a model family and researchers created many modified versions. The original BERT paper contains 2 main architecture sizes: BERT Base and BERT Large. A 2020 BERTology survey reviewed more than 150 studies about BERT behavior, training changes, architecture changes, and compression methods. DistilBERT is one verified compression example. Its paper reports a 40% smaller model that retains 97% of BERT’s language understanding capability and runs 60% faster.
BERT variants can be grouped into 6 main types.
| Variant type | Purpose | Examples |
|---|---|---|
| Original BERT | General language understanding | BERT Base, BERT Large |
| Compression variants | Reduce model size and inference cost | DistilBERT, TinyBERT |
| Training-objective variants | Change pre-training method | RoBERTa, ELECTRA, SpanBERT |
| Parameter-sharing variants | Reduce parameter count | ALBERT |
| Domain variants | Adapt BERT to one subject area | Legal, medical, financial BERT models |
| Language variants | Adapt BERT to one or more languages | Multilingual and single-language BERT models |
How google uses BERT To Rank Website’s?
Google uses BERT to rank websites by understanding combinations of words, meanings, and intent during Search result processing. BERT does not replace all ranking systems. Google states that its ranking systems use many factors and signals across hundreds of billions of pages. Google’s own examples show BERT handling prepositions and negation.
How you Use BERT To Increase Your Rankings?
To use BERT to increase rankings, increase semantic clarity between the query, heading, first answer sentence, entities, attributes, and supporting evidence. Ranking increases are not guaranteed, because Google uses many systems and signals, but semantic clarity improves query-content matching.
Use this 10-step BERT SEO process.
- Answer the heading first: Put the direct answer in the first sentence after every heading.
- Name the entity: Use the full entity name before shortening it.
- Define the attribute: State what the entity is, what it does, and where it applies.
- Connect words logically: Keep subject, verb, and object close.
- Use query terms naturally: Use exact terms where they carry meaning.
- Add related terms: Add entities such as model, training data, architecture, ranking, intent, query, snippet, token, and context.
- Separate similar concepts: Explain BERT, NLP, transformer, ranking system, and GPT separately.
- Use tables for comparison: Put dimensions, values, and differences in rows.
- Use examples after plural claims: After “ranking functions,” list the functions.
- Remove empty words: Delete sentences that do not Convery any meaning.
A BERT-friendly paragraph contains 5 parts: entity, definition, attribute, evidence, and implication. That paragraph works because every sentence keeps the same macro context: BERT, context, language understanding, query matching.
Example structure:
“BERT is a bidirectional Transformer encoder. BERT reads left and right context in each layer. This structure helps language systems understand word relationships in queries.”
What Is the Difference Between BERT Vs GPT?
The difference between BERT vs GPT is BERT is built for bidirectional language understanding, while GPT is built for left-to-right language generation. BERT uses an encoder structure and masked language modeling. GPT uses a generative pre-training method with language modeling and supervised fine-tuning.
| Feature | BERT | GPT |
|---|---|---|
| Full form | Bidirectional Encoder Representations from Transformers | Generative Pre-trained Transformer |
| Architecture type | Transformer encoder | Transformer decoder-style language model |
| Context direction | Left and right context | Previous-token context |
| Main training objective | Masked word prediction and sentence relation prediction | Next-token language modeling and fine-tuning |
| Main strength | Understanding text meaning | Generating text continuation |
| Search relevance | Query and content understanding | Generative answering and text production |